Strata v0.1.40.4 Restores Decode Speed on Pascal GPUs After Regression
The open-source engine making it possible to run 125-billion-parameter AI models on consumer hardware just shipped a targeted hotfix. Strata v0.1.40.4 landed on October 8, and it brings decode performance back to normal for users of older NVIDIA Pascal cards.
If you're running a Tesla P40, GTX 1080, or GTX 1070, the regression traced back to a commit intended for high-end silicon ended up halving your token speed. The fix restores full performance.
For those keeping score, Strata is the inference engine that lets you run Qwen3.8-Flash-Next locally without paying per-token fees. Maintained by Niko (Niko1221) in Ljubljana, the project has racked up roughly 17,900 stars on GitHub. The pitch is straightforward. You get an OpenAI-compatible API at http://127.0.0.1:8080/v1, full privacy, and a model that streams answers fast enough to outpace your own reading speed.
The regression, the cause, and the fix
Strata 0.1.40.4 is a single-purpose patch. The maintainer calls it a hotfix for v0.1.40.3. The culprit was commit 2e4ddf6, originally part of PR #904 to add verification window support for sm_90+ architectures. That change slipped through and applied to every CUDA architecture instead of just the target hardware.
Two things broke down on Pascal hardware. First, __restrict__ hints vanished from the compiled code. That stripped the read-only cache path, forcing the compiler to drop the LDG.nc load instruction. Second, a prefetch flag enabled itself on cards that can't overlap it, adding latency to every decode step.
The result was a measurable bottleneck at the instruction level. A SASS comparison of the affected kernel showed instruction counts jumping from 231,348 to 373,044. Read-only loads collapsed while plain L2 loads surged. Pascal chips lack the L1 caching for ordinary global loads that newer cards possess, so losing the read-only path meant every block re-read activation data from the slower cache tier. Not cheap in terms of time.
The fix didn't come from the maintainer's desk. Niko doesn't have a Pascal card to test against. The diagnosis came from two community members who dug through the commits.
paulhothersall isolated the issue on a Tesla P40, measuring decode drop from 36.4 tok/s down to 17.7 tok/s. They bisected roughly 125 commits and found the offender. lineape confirmed the regression on a dual-GTX 1080 and 1070 setup, running rigorous A/B tests with alternating arms within a single session. Both validated a two-line restore of the read-only hint and the prefetch flag, recovering full performance. And that's exactly what happened here.
Head here to the pull requests where the community workups read like peer-reviewed engineering post-mortems.
Modern cards unaffected
If you're rocking an RTX 3080 or newer, this release is essentially a no-op. The compiled code in v0.1.40.4 is byte-identical to 0.1.40.3 for any card at sm_70 or above. Your RTX 3080 decode numbers, sitting around 74 tok/s in the testers' benchmarks, remain unchanged.
The patch targets cards below sm_70 exclusively. You can skip this update if you're on an RTX 20, 30, 40, or 50 series. Strata says the default answers are unchanged across the board anyway.
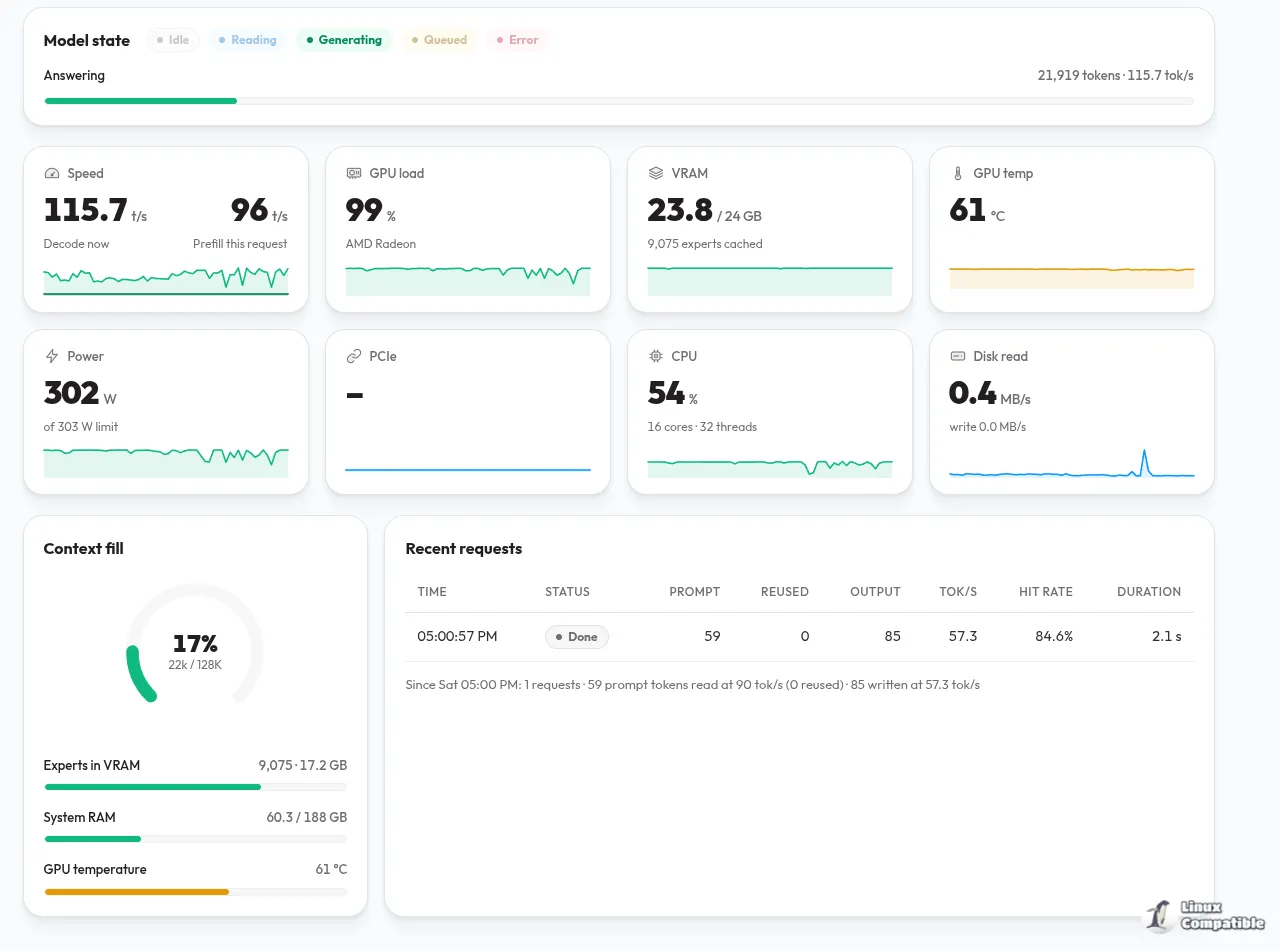
Installation remains frictionless. Linux users run ./setup.sh. The installer auto-detects your GPU, grabs about 70 GB of model weights, and opens your browser to the local API. You get a chat interface, a monitor for GPU and CPU usage, and full access to the endpoint.
Keep in mind that you need 12 GB of VRAM and 32 GB of RAM to run the model comfortably. The model weights take up roughly 70 GB, so plan for 80 GB of free disk space with an SSD preferred. Older cards work experimentally, but Pascal is where the real performance story is right now.
Strata v0.1.40.4 is available now on GitHub. The 0.1.40 series continues to roll out fixes at a rapid clip, with performance patches landing faster than most users can read them. You can run a 125B model locally at 53 to 94 tok/s on an RTX 5070. The long wait for accessible local AI just keeps getting shorter.


