Strata 0.2.8: The viral 125B local AI engine runs faster on consumer graphics cards
The fast-growing open-source engine Strata shipped version 0.2.8 on October 29, bringing multi-GPU speed-ups for Intel Arc and AMD Radeon cards, a fix for a Mac memory leak, and better handling of the tool calls that let an AI drive other software.
Strata runs Qwen3.8-Flash-Next, an Alibaba model of roughly 125 billion parameters, on hardware most people would call a gaming PC. 12 gigabytes of VRAM and 32 GB of RAM is the floor. That'd normally take a data center. Instead it takes a single MIT-licensed repo, an offline install, and a localhost API.
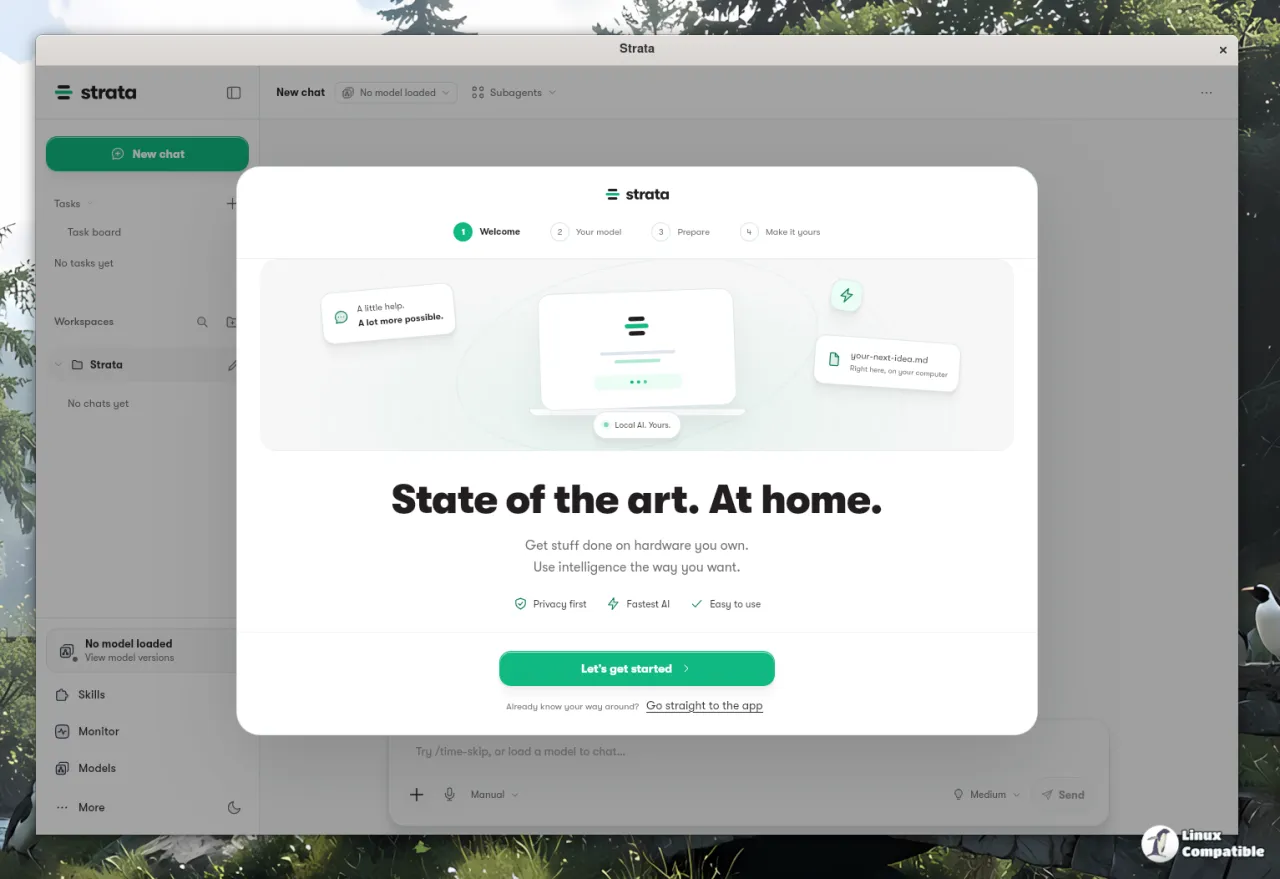
Since Niko Veit opened the repository on September 24, the project has climbed to about 36,000 GitHub stars in roughly five weeks. That's one of the quickest climbs on record for a local-AI project, and it's largely a one-person effort funded through Buy Me A Coffee. Keep in mind that "one person" and "36,000 stars" don't usually sit in the same sentence.
The numbers that actually matter
Veit's release notes are unusually honest about what was and wasn't tested, which is rare in a benchmark-obsessed corner of tech. The headline results apply to very specific setups, and he says so up front.
Two Intel Arc Pro B65 cards now decode 17% to 23% faster. Chat sits at 71 to 74 tokens per second, up from 60 to 63, with JSON at 80 to 83 tok/s. Those tests used exactly two B-series cards. A single card, an A-series card, or three or more don't benefit. They run exactly as before.
Four Radeon AI PRO R9700 cards tell a different story. At 32 simultaneous requests, total throughput jumps 2.4x, from 155 to 370 tok/s combined. Individual replies don't get faster, though. One request still runs around 67 tok/s. What this buys you is concurrency, not per-request speed. Worth keeping that straight.
On the Mac, DeepSeek was leaking roughly 1.3 GB of GPU buffers with every request. Run it long enough and memory fills, decode crawls from 16 down to 3 tokens per second, and your afternoon is gone. Strata now holds steady at 76 GB across 34 requests, decode steady at 18 to 22 tok/s, answers unchanged. The tests ran on an M5 Max with 128 GB, not a 256 GB Mac Studio.
Tool-call recovery is now on by default and catches 98.3% of agent turns, up from 92.9%. This only applies to tools the request actually declared.
There's also a quiet reversal. A 0.2.7 change had made answers faster on RTX cards with 12 GB or less, but the speed came at the cost of repeated text in long sessions. Strata routes exactly as 0.2.6 does now, with the option back on through a toggle or the STRATA_ROUTE_PRIOR=1.5 flag. Not cheap to admit, but the candor is the point.
Why the approach works
The interesting part of Strata isn't any single benchmark. It's the idea behind it.
Qwen3.8-Flash-Next has 48 layers and 24,576 experts in total, activating only about 10 per token. Strata spreads those experts across three tiers of a typical PC at once: VRAM on the GPU, pinned system RAM on the CPU, and a roughly 28.8 GB n-gram table on the SSD. The goal, in the project's own words, is to make "the GPU, the CPU, the RAM and the PCIe link all busy with the work each is best at."
The key realization is that VRAM matters more than raw GPU speed. Each extra gigabyte holds about 700 more experts, and every expert already sitting on the GPU is one the CPU doesn't have to crunch. The whole engine is tuned around cramming as many experts as possible into video memory.
Strata also guesses. Its model carries a small multi-token-prediction layer that drafts the next few words while the full 48-layer model checks them in one pass. It keeps what's right and writes the rest itself, typically landing 1.6 to 1.8x sooner. That's speculative decoding, an older trick that Strata simply applies to a model built for exactly this.
Caveats. A lot of them.
This is where the honest reporting pays off. Aggressive quantization costs quality, and users have seen it. Different runs of the same prompt can also word answers differently, because which experts live in VRAM shifts from moment to moment.
The practical baseline is 12 GB of VRAM, though 8 GB technically runs. 64 GB of RAM is the realistic recommendation, not the 32 GB minimum. Disk use starts near 80 GB and climbs past 150 with bigger quantizations. macOS is experimental and built from source, as is Intel Arc and AMD's Strix Halo. First launch loads 35 to 55 GB into RAM and locks part of it, which can freeze your PC for a minute or three. Expected, not a bug.
Head here to the GitHub repo for the full release notes and downloads.


