Strata 0.2.9: 1-bit DeepSeek, Faster NVIDIA Requests, and Cheap AMD Multi-GPU Support
The open-source local AI inference engine adds AMD Strix Halo prompt speedups, multi-GPU fixes, and Unsloth's 1-bit DeepSeek quantization.
The latest update of the open-source engine from developer Niko Veit dropped today, alongside engine and Control builds at 0.1.55. No cloud account. No monthly fee. A one-click installer that still downloads a large chunk of the model on first launch, that's the tradeoff.
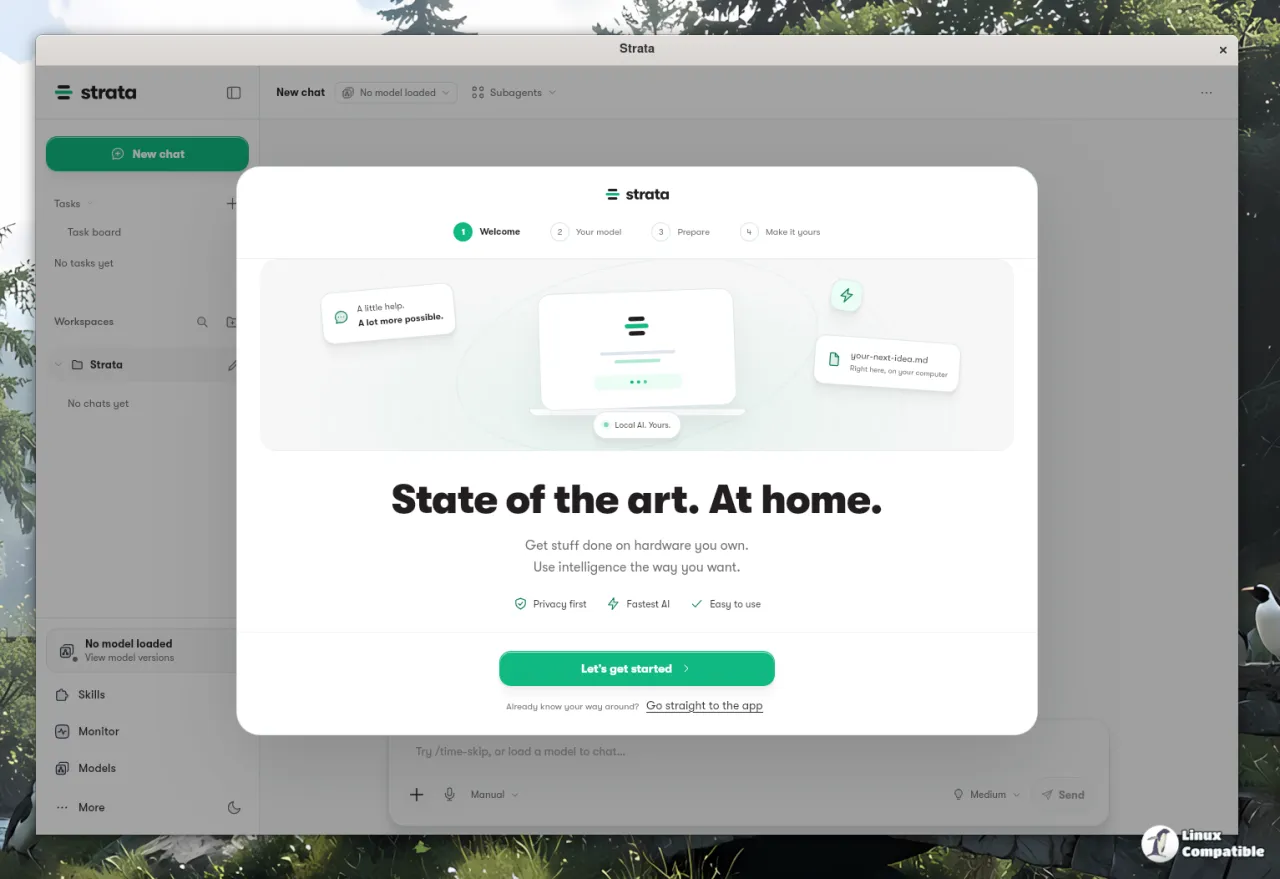
Strata's whole pitch is that frontier models don't have to live in the data center. Qwen3.8-Flash-Next, the flagship it targets, normally needs hundreds of GB of VRAM, which means a rack of server GPUs. Strata instead spreads the load across your GPU, your system RAM, and your SSD. Any given word only needs a small slice of the model, so it never has to hold all of itself at once.
The trick is a mixture-of-experts design. Qwen3.8-Flash-Next has up to 24,576 experts. A single token activates only a handful of them. That sparsity is what lets a model this big run on hardware that couldn't hold it in full.
Strata 0.2.9 by the numbers
The Strix Halo path on Windows got by far the biggest jump. Against the previous engine, Strata's own tests show Qwen3.8 on an 8K prompt climbing from 791 to 1,424 tokens per second. That's roughly 1.8× faster. A 32K prompt goes from 778 to 1,460 tok/s. Decode barely moved: 57.4 to 58.9 tokens per second, squarely within normal spread.
Parallel requests on Linux NVIDIA GPUs are now 1.45× faster, which matters if you're actually juggling several calls. A single request is only about 5% faster on its own. New default kernels also nudge Linux prompts 2 to 6% faster, with Intel Arc cards seeing the steepest gains at 4.6 to 15.8%.
The one that'll draw attention is multi-GPU on cheap AMD cards. Four Radeon AI PRO R9700s previously ran on a single card, 2,371 of 15,360 experts, decode in the single digits. Now Strata fills all four by default, with no --gpu flag, and decode climbs to 57.7–103.7 tok/s. Four modest cards suddenly act like one accelerator.
1-bit DeepSeek goes selectable
Unsloth's 1-bit quantized DeepSeek models are now a usable option, compressing a 763-billion-parameter model down to roughly 240 GB. Downloads land at 241 GB for UD-IQ1_S and 258 GB for UD-IQ1_M, about 111 GB cheaper if you already own ISTA's Engram file.
The quality hit is smaller than you'd expect. Against Unsloth's own Q8 reference, the 1-bit sets score 87 to 89% top-1 agreement, with perplexity up just 3 to 5%. On a 61-task suite both 1-bit variants get 53, versus 56 for ISTA's 2-bit set. The gap is mostly in extraction and summary work.
The project has been on a strange trajectory since it hit GitHub in late September. It pulled roughly 10,700 stars in a matter of days. As of this writing the repo sits at around 36,700 stars and 4,000 forks, with over 4,900 commits and 502 open issues. It's MIT-licensed and funded partly through a Buy Me A Coffee link, which is a small era-defining detail you don't often see at this scale.
Head here to the GitHub release announcement.


